Soumyabrata Chaudhuri (Soumya)I’m currently a MS in Computer Science (Thesis) student at UT Austin, where I work with Prof. Joydeep Ghosh. I’m broadly interested in multimodal large language models (MLLMs) and multi-agent systems. During my masters, my work has spanned multimodal reasoning, the evaluation and analysis of MLLMs, efficient VLM/LLMs, and also diffusion models (dLMs, dMLLMs, and image/video generative models). I also spent a summer at Amazon as an Applied Scientist Intern. Before that, I completed my B.Tech (Honors) degree in Computer Science and Engineering at Indian Institute of Technology (IIT), Bhubaneswar, where my thesis received the Best Thesis Award from the Department of Computer Science. During my undergraduate studies, I conducted research across interrelated domains, including Machine Learning, Computer Vision, Natural Language Processing, and Multi-Modal Learning. For my B.Tech thesis, I collaborated with Microsoft India to improve the travel-planning process using large language models, under the supervision of Dr. Shreya Ghosh, Dr. Abhik Jana, and Dr. Manish Gupta. I spent a wonderful summer interning at the University of Alberta’s Vision and Learning Lab (MITACS GRI), where I worked with Prof. Li Cheng on motion imitation learning and text-to-3D motion generation. I also had an enriching research internship at IIT Kharagpur, collaborating with Dr. Saumik Bhattacharya on multi-modal learning and action recognition in videos. Email / GitHub / Google Scholar / Resume / LinkedIn / |
|
Affiliations / Collaborations
2025–present 
Summer 2026 
2024–2025 
Summer 2024 
2023–2025 
2021–2025 |
News
|
Research'*' indicates equal contribution. |
|
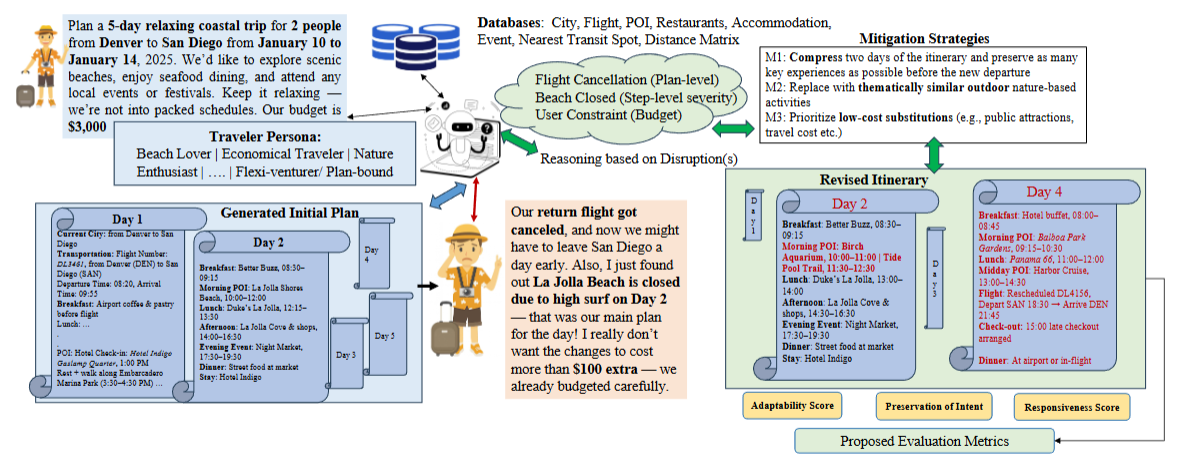
TripTide: A Benchmark for Adaptive Travel Planning under DisruptionsPriyanshu Karmakar, Soumyabrata Chaudhuri, Shubhojit Mallick, Manish Gupta, Abhik Jana, Shreya Ghosh ACL (Findings), 2026 paper / code / We introduce TripTide, the first benchmark specifically designed to evaluate LLMs’ ability to adapt itineraries in the face of realistic disruptions. TripTide models key dimensions such as disruption severity levels and traveler tolerance profiles, enabling nuanced assessment of LLM responses to unexpected events like transit cancellations, weather-related closures, or overbooked attractions. |
|
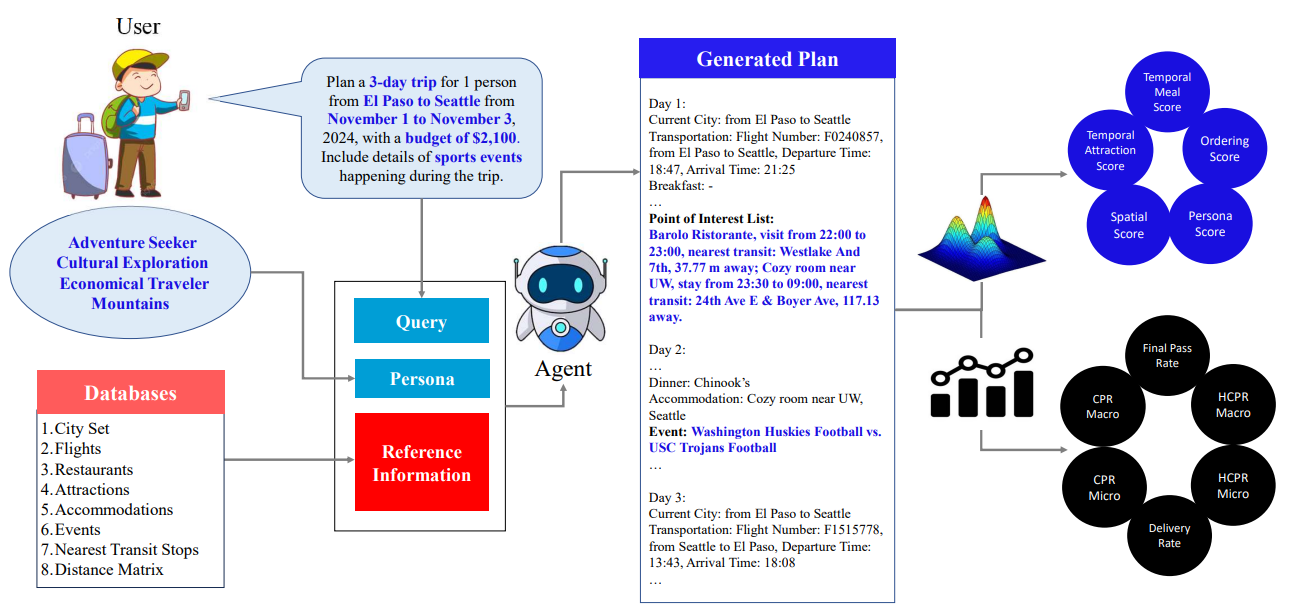
TripCraft: A Benchmark for Spatio-Temporally Fine Grained Travel PlanningSoumyabrata Chaudhuri, Pranav Purkar, Ritwik Raghav, Shubhojit Mallick, Manish Gupta, Abhik Jana, Shreya Ghosh ACL (Main), 2025 paper / code / We introduce TripCraft, a spatiotemporally coherent travel planning dataset for Large Language Models (LLMs) that integrates real world constraints, including public transit schedules, event availability, diverse attraction categories, and user personas for enhanced personalization. |
|
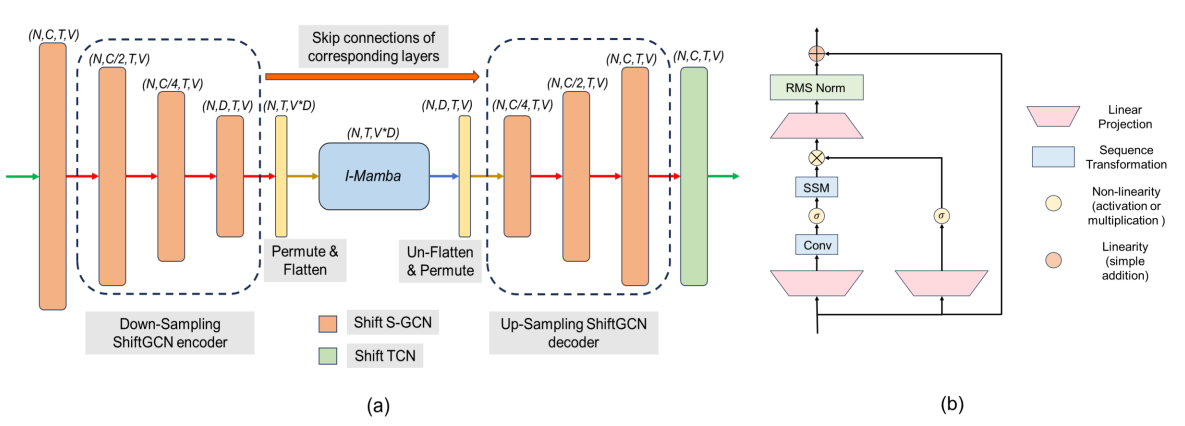
Simba: Mamba augmented U-ShiftGCN for Skeletal Action Recognition in VideosSoumyabrata Chaudhuri, Saumik Bhattacharya arxiv, 2024 paper / code / Simba is the inaugural attempt at leveraging the Mamba model for skeleton action recognition task in videos. |
|
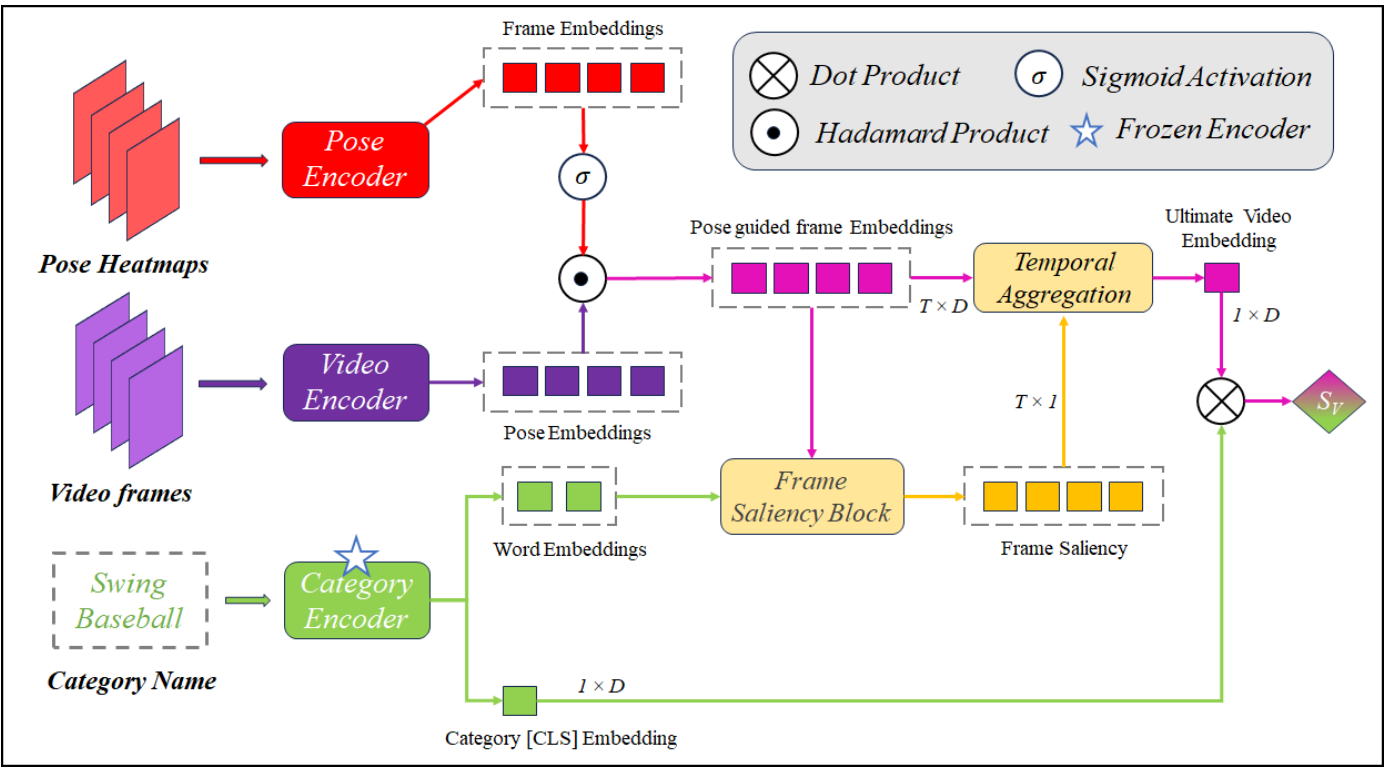
ViLP: Knowledge Exploration using Vision, Language and Pose Embeddings for Video Action RecognitionSoumyabrata Chaudhuri, Saumik Bhattacharya ACM ICVGIP (Oral), 2023 paper / code / ViLP explores cross-modal knowledge from the pre-trained vision-language model (e.g., CLIP) to introduce the novel combination of pose, visual information, and text attributes. |
|
Design and source code from Leonid Keselman's website |